OCR API, pay per page, no subscription: $0.003 per page
Most OCR services want a monthly plan, a cloud account with a billing profile, or a minimum spend. If you have a pile of scans once a quarter, that is a poor fit. This guide covers a pay-per-page option: you send links to images or scanned PDFs, you get the text of every page back as JSON, and you pay $0.003 for each page that had text. Pages with no text, files that fail to open and links that cannot be fetched are returned with the reason and are not charged.
What it is
An Apify Actor that runs the open-source Tesseract 5 engine (Apache-2.0) inside the Actor, with 27 languages built in. Your files are not sent to any third-party OCR service. It reads PNG, JPEG, TIFF (multi-page too), GIF, BMP, WebP and PDF, and you can call it from the Apify API, a spreadsheet script, n8n, Make or by hand in the Apify console.
Price
| Job | Cost |
|---|---|
| 1 scanned letter | $0.003 |
| A 40-page scanned contract | $0.12 |
| 1,000 receipts | $3.00 |
| Blank pages, photos without text, broken files | $0, returned with a failure reason |
There is no start fee and no monthly plan. The Apify free plan includes monthly credit, so you can try it before paying anything. Set a maximum spend per run and the Actor stops when it is reached.
A real run: a scanned business letter
We made a sample letter with made-up text, saved it as an image, and ran the Actor on it from Apify's servers on 2 November 2026. The input:
{"urls": [{"url": "https://keencrest-guides.web.app/samples/sample-scan.png"}], "languages": ["eng"]}You can open the image and compare. The output row came back with status: ok, confidence: 95.8, 67 words, 408 characters, and this text (middle shortened):
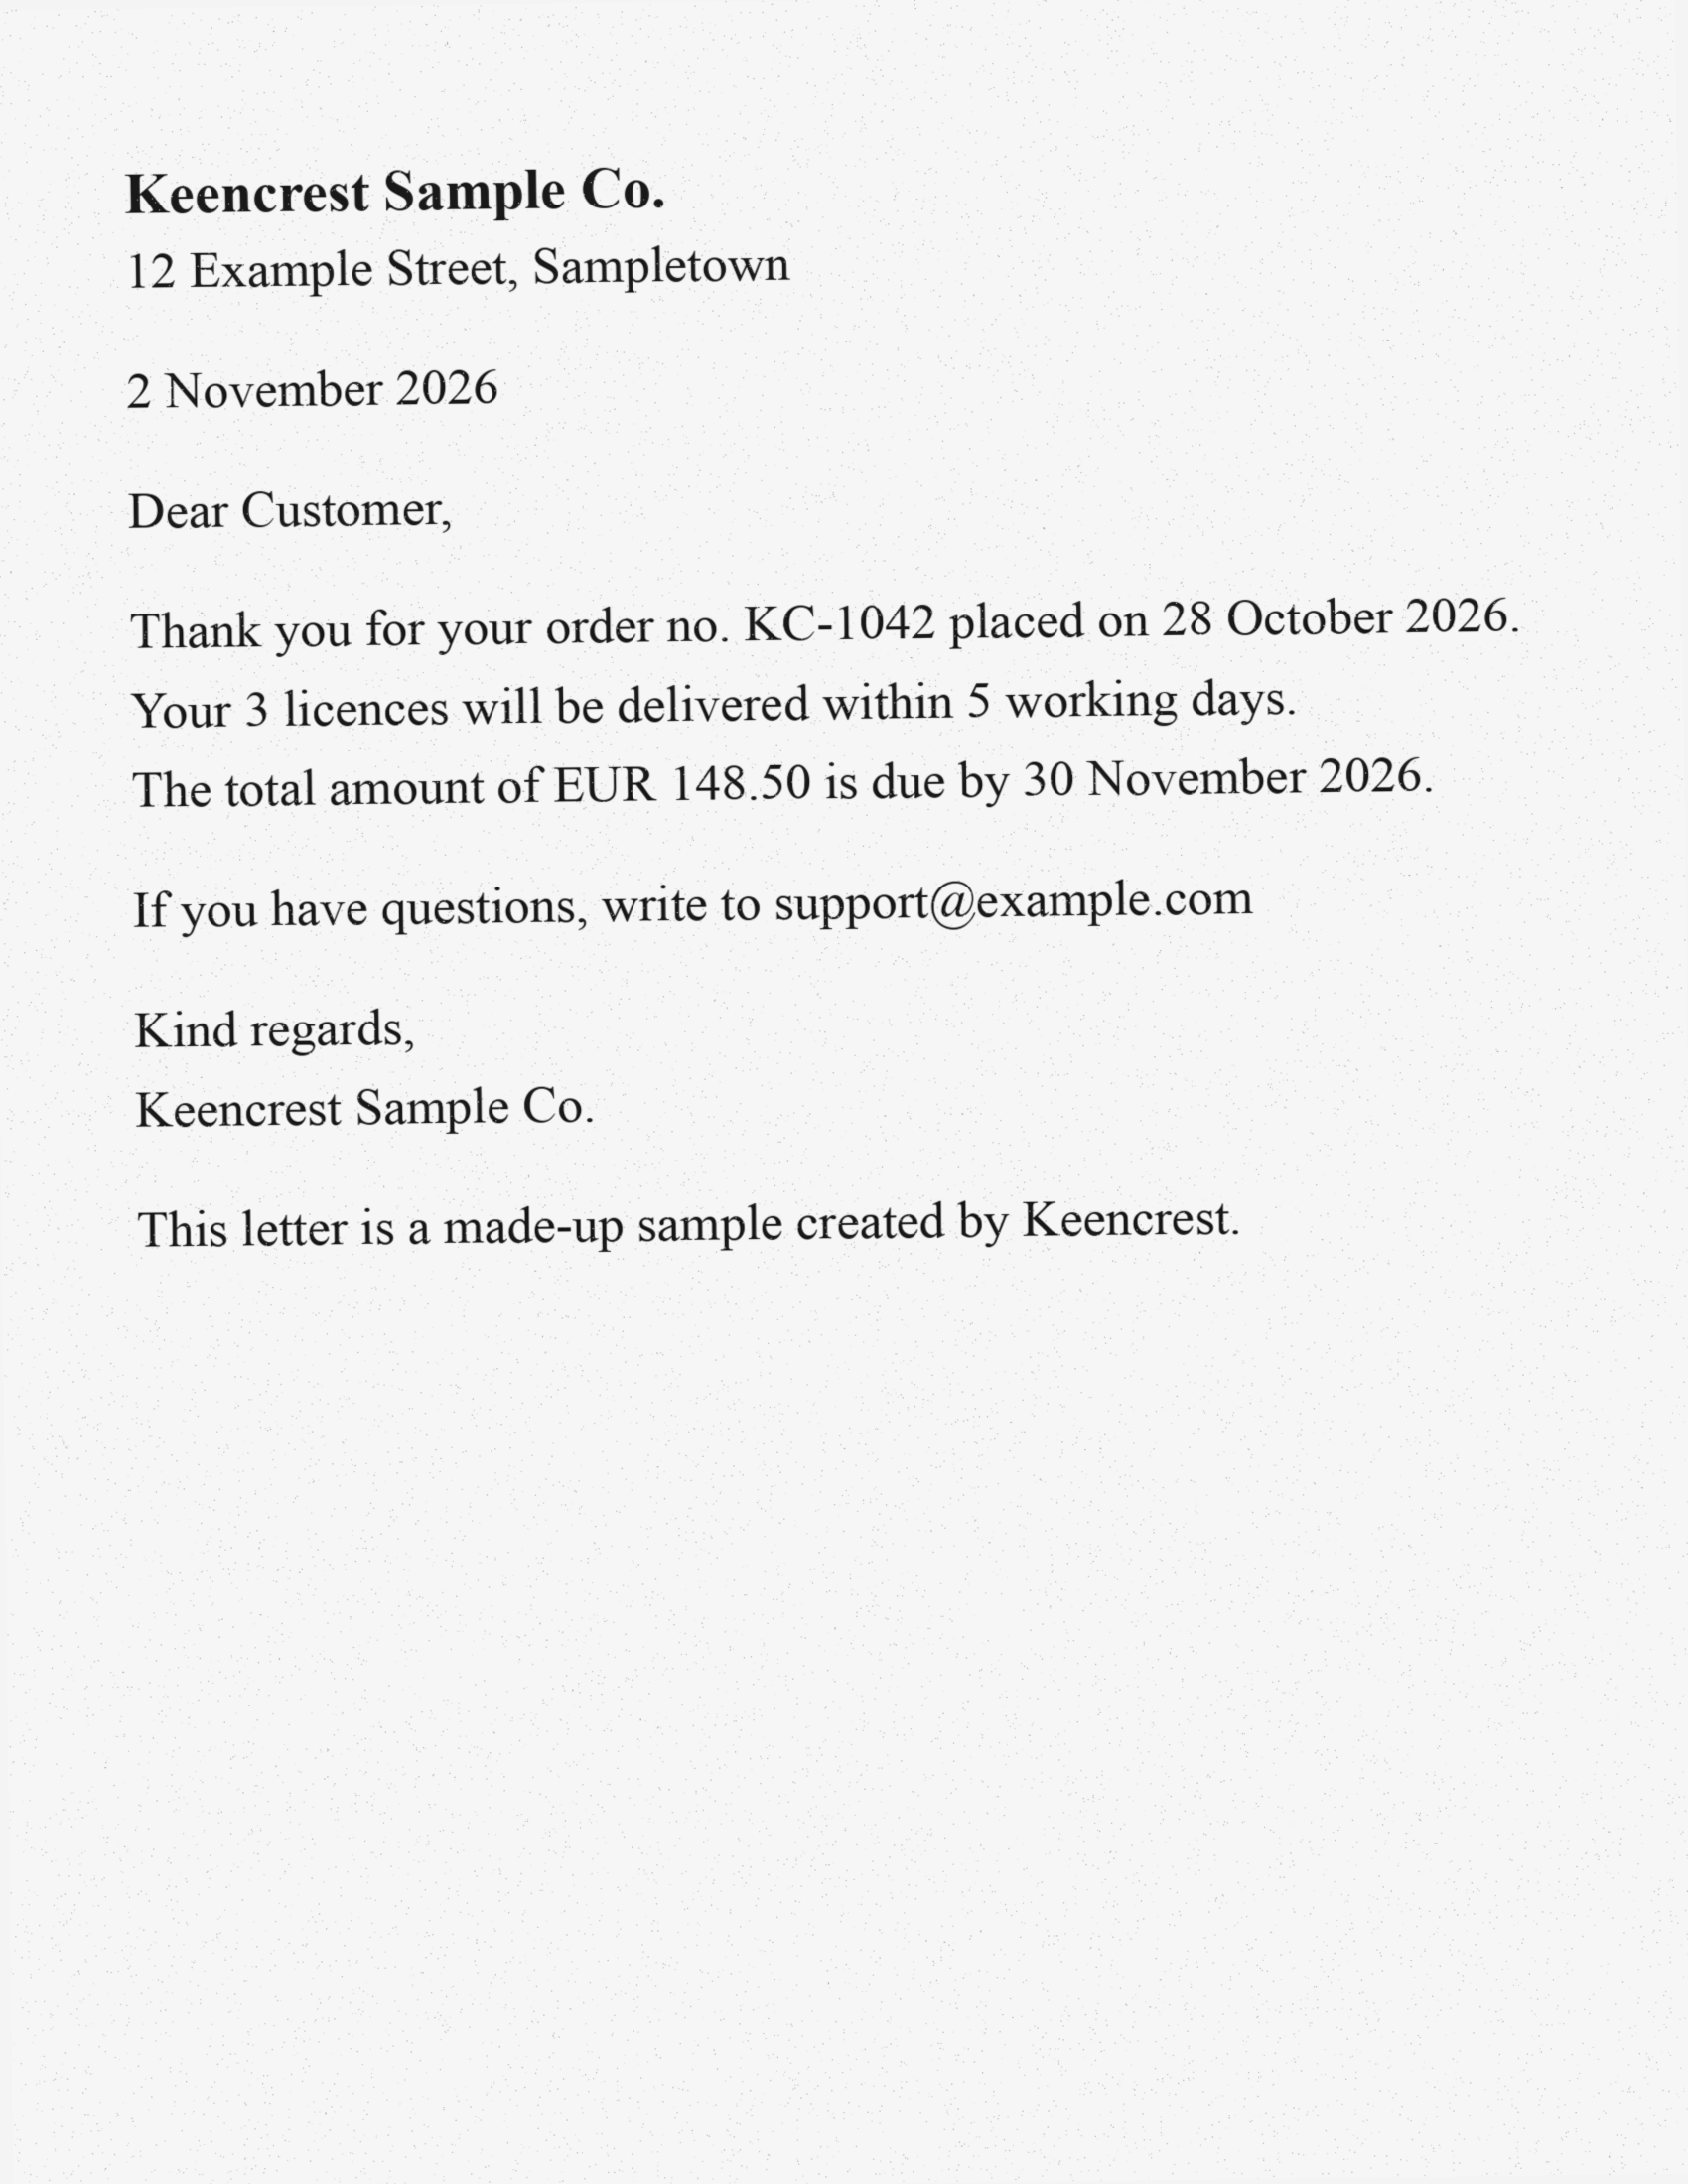
Keencrest Sample Co.
12 Example Street, Sampletown

2 November 2026
Dear Customer,

Thank you for your order no. KC-1042 placed on 28 October 2026.
Your 3 licences will be delivered within 5 working days.
The total amount of EUR 148.50 is due by 30 November 2026.
...
This letter is a made-up sample created by Keencrest.
Every line matched the image. The row also carries the image size, the page number and count for PDFs, billed: true, and optional word boxes if you set includeWordBoxes.
A mixed German and English letter
For a letter in two languages, list both: "languages": ["deu", "eng"]. On the German and English sample the run returned confidence 96.1 and read the umlauts, the sharp s and the euro sign correctly:
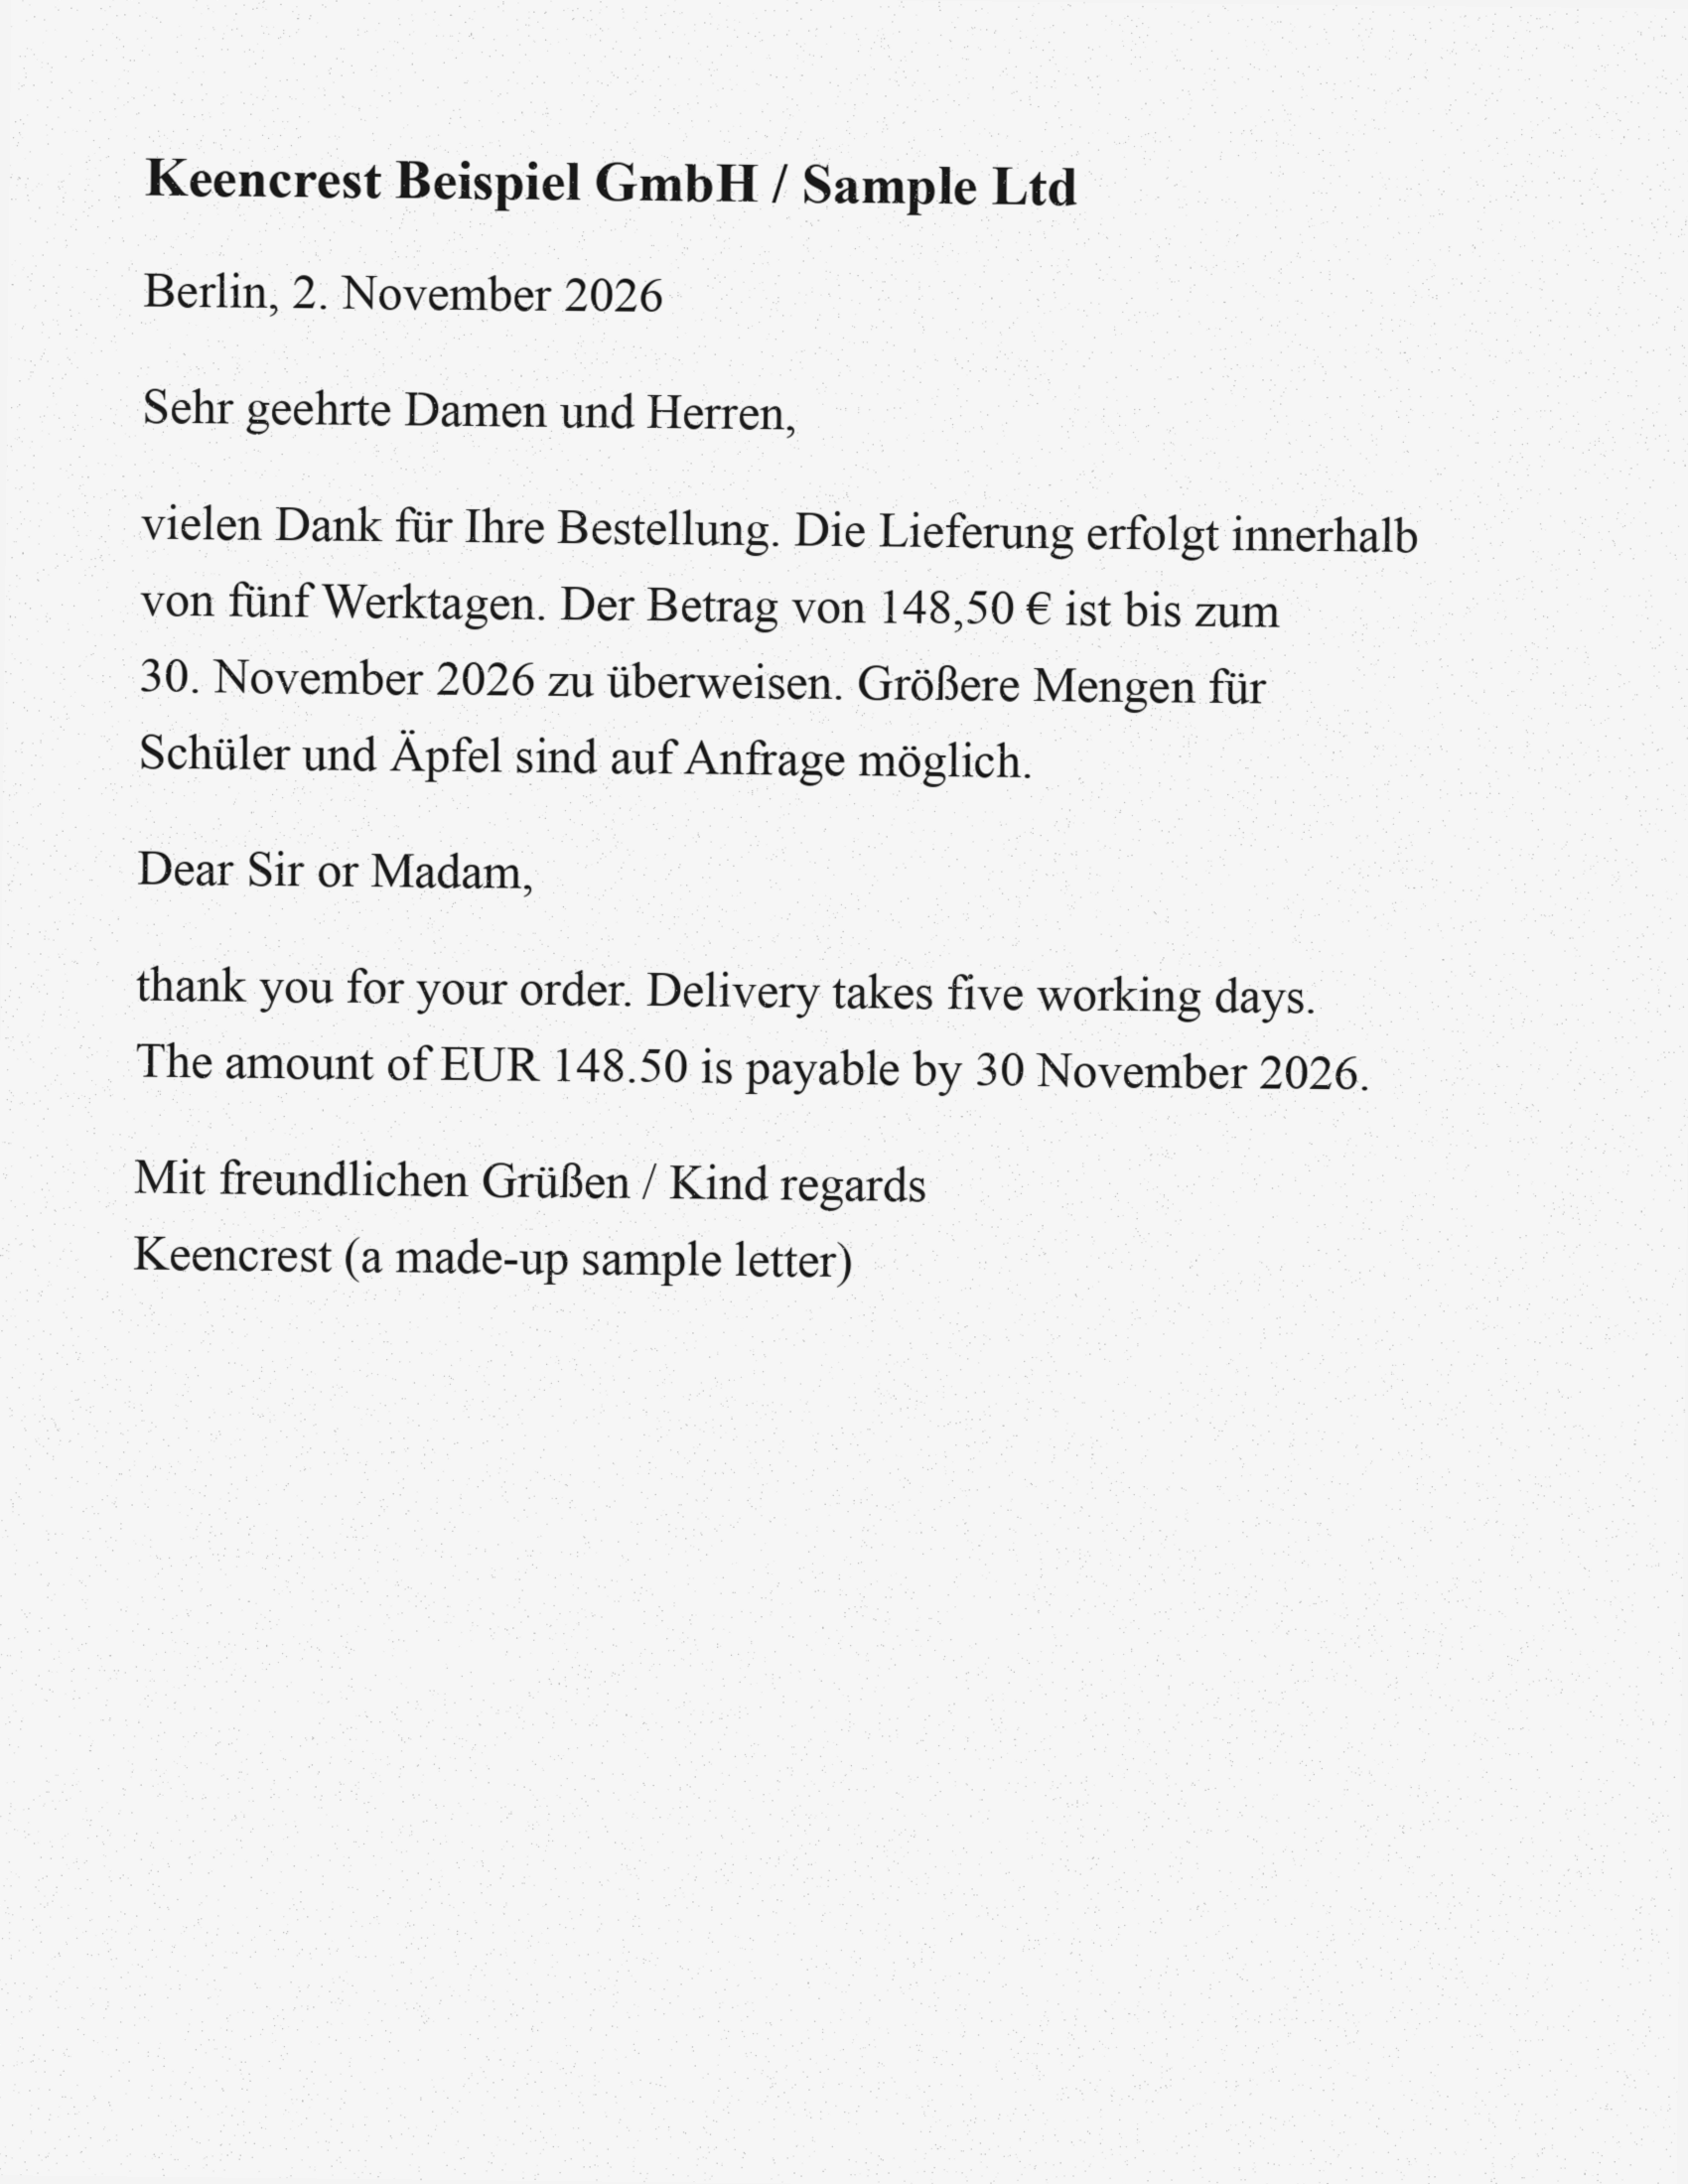
vielen Dank für Ihre Bestellung. Die Lieferung erfolgt innerhalb
von fünf Werktagen. Der Betrag von 148,50 € ist bis zum
30. November 2026 zu überweisen. Größere Mengen für
Schüler und Äpfel sind auf Anfrage möglich.
Where it makes mistakes: a receipt
Here is a result that is not perfect, because you should know what to check. On our sample receipt in default mode the confidence was 90.7 and the totals read correctly, but one line was garbled. The image says Coffee 2 x 3.20 6.40; the output said:
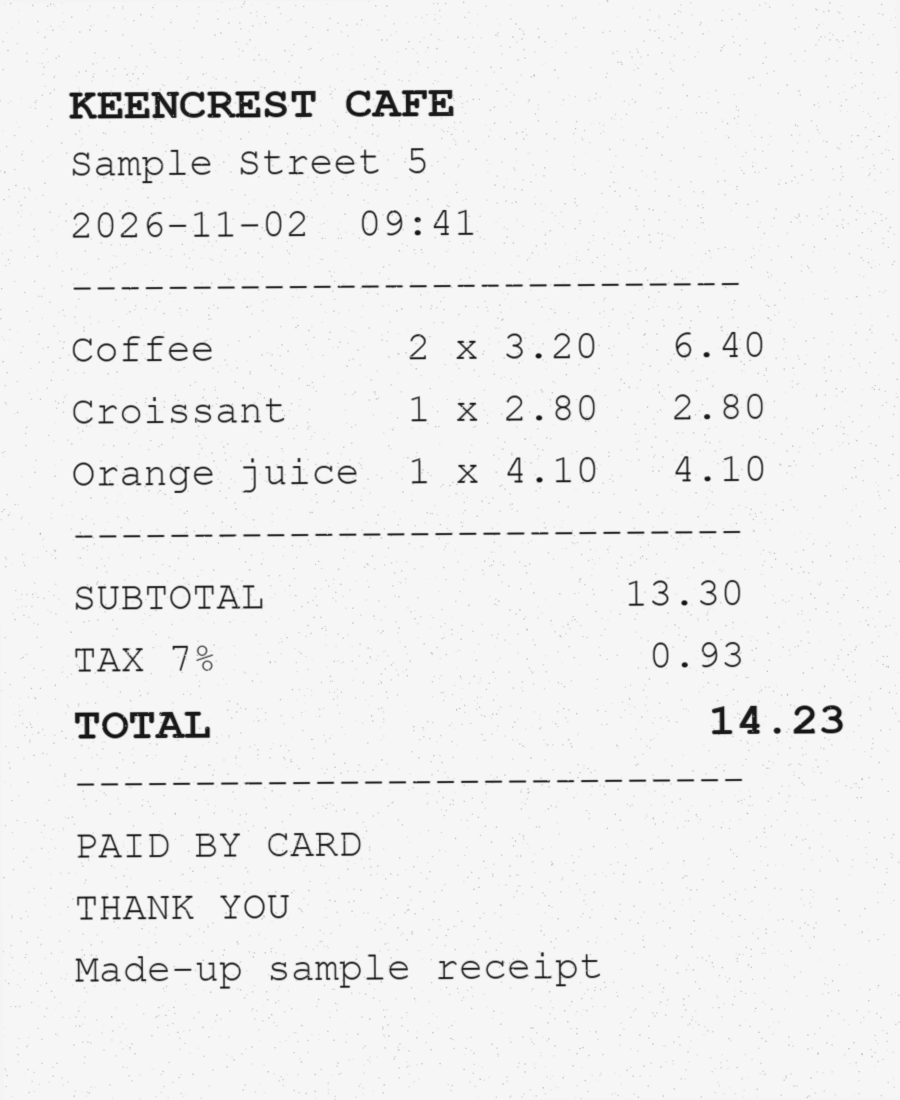
Coffee 2 ¥& SoBl 6.40
Croissant 1 x 2.80 2.80
Orange juice 1 x 4.10 4.10
SUBTOTAL 13.30   TAX 7% 0.93   TOTAL 14.23
We left it as it is. A line whose quantity and price no longer multiply to its total is the kind of error to catch by checking arithmetic after the run. For receipts and labels the single_block setting of pageSegmentationMode is the one to try first (it scored 90.9 on this sample and still garbled that line), and re-running a low-confidence page costs $0.003.
Limits to know
- Quality depends on the scan. Straight, 300 DPI, high-contrast printed text reads best. Handwriting is not supported in practice and photos taken at an angle read poorly. Treat a
confidenceunder about 60 as a poor scan. - Every page of a PDF is OCR'd, even when it already has a text layer. For digital PDFs with a text layer, PDF to Markdown is faster and charges per document.
- A dense A4 page takes about 16 seconds at the default 1 GB of memory and about 4 seconds at 4 GB. The price per page is the same, so give big batches more memory.
- It fetches files from links you provide and obeys the host's robots.txt; hosts whose terms forbid automated downloads are refused with a clear reason (not charged). Upload your own files to a key-value store or use a link on a site you control.
- Do not send documents you have no right to process. Scans that hold other people's personal data carry your own legal duties.
How to run it
- Put your files at public links (or upload them to an Apify key-value store).
- Open the Actor, paste the links into
urls, pick the languages, and run. Start with 3 to 5 files and checkconfidence. - Export the dataset as JSON, CSV or Excel, or fetch it through the API.
Try it: OCR: Images & Scanned PDFs to Text on Apify. $0.003 per page with text, nothing for pages without. The Apify free plan includes monthly credit, so a test run costs nothing out of pocket.
Related guides
- Find a company's website from its name (bulk): 96% on known companies, $0.80 per 1,000 found
- Company names to business emails (bulk): 11 of 20 names, $0.04 measured
- Find contact forms on a list of websites: contact page, form type, captcha
- Find a Google Play app's competitors and similar apps, with installs: $0.30 per 1,000 apps
- Export a Google Play developer's app list and a category's competitor apps, with installs and ratings
- FMCSA insurance cancellation list and MC suspension list: what it is and how to pull it